
An application server, fine for two years, starts losing its main process every few days after the machine is rebuilt on a newer release. The service log ends mid-request with no error, dmesg shows no OOM kill, and free -h, checked afterwards, shows several gigabytes available — which convinces everyone this is not a memory problem and costs about a fortnight. It was a memory problem, in stage 5 of the eight this page follows, and the OOM killer — which gets all the attention — was never involved. It is the least interesting part of Linux memory management, the last thing that happens after several other mechanisms have tried and failed; reading about it first is like learning about a house fire by studying the smoke alarm.
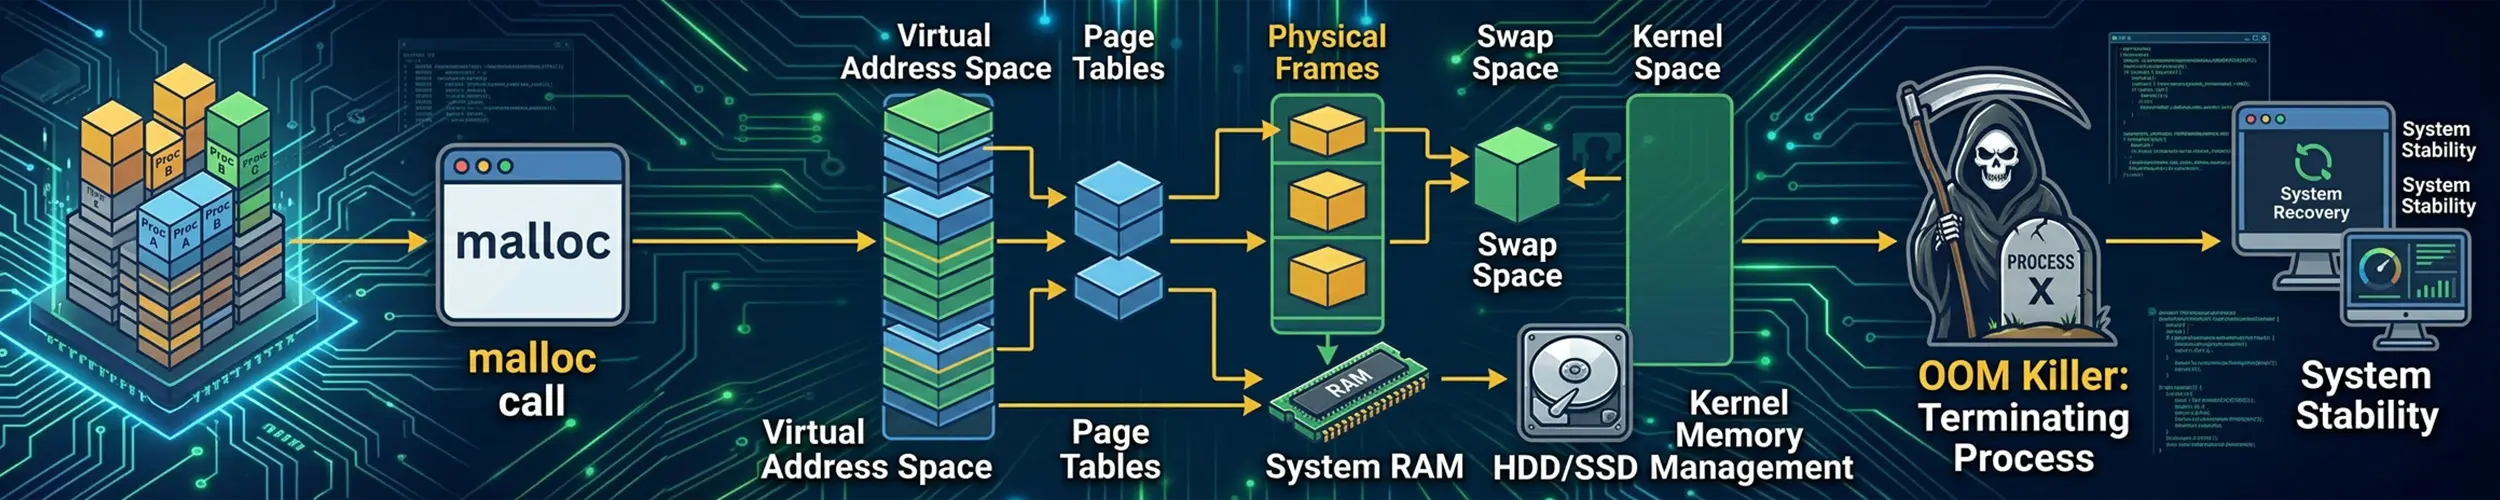
This page follows a single page of memory from a program asking for it to the kernel taking it back — eight stages, in order. Nearly every memory problem worth diagnosing lives in stages 1 to 7, and most of them look identical from the outside until you ask one question. If you have not read memory, swap and the OOM killer, start there — it covers why free looks alarming and what overcommit promises. This one goes a full level below it.
The eight stages. Every section below is one of them, in order.
- The allocator asks.
mallocdecides whether to extend the heap or make a new mapping. No kernel involvement for most calls. - An address range appears. The kernel records a promise. No physical memory has been touched.
- A page fault makes it real. The first access assigns an actual physical page.
- The page has a kind and a size. Anonymous or file-backed; a base page, a huge page, or a large folio.
- It ages on a list. Active or inactive, anon or file — and this is where
swappinessapplies. - Pressure builds and reclaim runs. In the background if you are lucky, in your own process if you are not.
- It is compressed, or written to swap. Or refused, if a cgroup says so.
- Something is killed. Usually by userspace before the kernel ever gets there.
The diagnostic hinge: ask whether anything is actually waiting.
cat /proc/pressure/memory
some avg10=0.00 avg60=0.00 avg300=0.00 total=1234
full avg10=0.00 avg60=0.00 avg300=0.00 total=567free reports a quantity. Pressure Stall Information reports a delay, and only the second one is evidence. If full is near zero, the machine is not short of memory — however frightening free -h looks — and whatever is wrong lives in stages 1 to 4: how memory is being allocated, mapped, sized or counted. If full is sustained above a few per cent, reclaim genuinely cannot keep up, and the problem is stages 5 to 8.
The kernel’s own definitions: some is the share of time in which at least some tasks are stalled on memory, full the share in which all non-idle tasks are. Some stalling is normal on any busy machine. Sustained full means nothing is running because everything is waiting — and for scale, systemd-oomd’s default is to start killing at 60% sustained over 30 seconds. That is the point at which something dies, not the point at which something is wrong.
The misreading worth correcting first: free‘s used column is not what you were taught. Every old article explains that used is total minus free minus buffers and cache; current free does not compute it that way at all, and its manual page is explicit that used is total - available. So the honest reading is simpler than the folklore: ignore free, read available — the kernel’s own estimate, in /proc/meminfo since Linux 3.14, of how much memory a new application could have without swapping, accounting for reclaimable cache and for the slab that is not reclaimable. And a lot of RAM belongs to no process at all — slab, page tables, Percpu, network buffers, SecPageTables on a virtualisation host, and compressed pages in zram or zswap — so adding up every RSS will never reach the total.
Stage 1 — The allocator asks
Most malloc calls never reach the kernel. glibc keeps a heap and hands out pieces of it, going to the kernel only when it needs more — brk to extend the heap, or a fresh mmap for large requests.
The threshold between those two is where the first widely repeated half-truth lives. M_MMAP_THRESHOLD starts at 128 KiB, and it is dynamic. When a program frees a block larger than the current threshold, glibc raises the threshold to that size, so a process that once freed a 4 MB buffer will thereafter satisfy 4 MB requests from the heap rather than a fresh mapping — which is why a long-running process’s allocation behaviour drifts, and why memory that “should” have been returned by munmap quietly stops being.
The second surprise is arenas. glibc gives threads separate heaps to reduce lock contention, and the default ceiling on a 64-bit machine is eight times the number of cores — up to 512 arenas on a 64-core box, each with its own reservation and its own independently trimmed top. Memory freed in one arena cannot be reused by a thread bound to another. This is the usual answer to “why does my threaded service have such a large RSS for what it is doing”.
# The standard mitigation for arena-driven RSS
MALLOC_ARENA_MAX=2 ./myservice

# What the process actually has mapped, cheaply
cat /proc/<pid>/smaps_rollup

# Watch the heap grow without it
strace -e trace=brk,mmap,munmap -p <pid>glibc returns memory to the kernel in only two situations: munmap of a mapping it made above the threshold, and trimming the top of a heap when the free run there exceeds M_TRIM_THRESHOLD. Fragmentation below the top is never returned on its own. malloc_trim() is still the practical answer, and since glibc 2.8 it works across every arena rather than only the main one.
On the alternatives, one story reversed and is worth getting right. jemalloc was archived in June 2025, with a postmortem from its author saying upstream development had ended — and then Meta unarchived it on 2 March 2026, with 5.3.1 shipping on 13 April 2026. So both “jemalloc is dead” and “nothing happened” are wrong, depending on when you last looked. mimalloc is actively maintained on the v3 branch; Google’s tcmalloc publishes no tagged releases by design, so I could not confirm its activity either way.
One recent change deserves a flag because it happened underneath people: glibc 2.43, in January 2026, enabled 2 MB transparent huge pages by default in malloc on AArch64. If you run arm64 servers, your allocator’s page-size behaviour changed without you asking, and it interacts with everything in stage 4.
Stage 2 — An address range appears
When glibc does call mmap, the kernel writes down a range and returns. No physical memory is allocated and nothing is zeroed. This is why allocating a gigabyte almost never fails, and why VSZ is close to meaningless as a memory figure.
How far the kernel will let that promise run is vm.overcommit_memory:
| Mode | Behaviour | In practice |
|---|---|---|
| 0 (default) | Heuristic — obvious overcommits refused | Almost everything succeeds |
| 1 | Always overcommit | For workloads that map far more than they touch |
| 2 | Never overcommit | Total commit capped at swap + ratio% × RAM |
Mode 2 is the one people reach for after being burned by the OOM killer, and it has a trap. vm.overcommit_ratio defaults to 50, so on a machine with no swap, strict mode refuses allocations past half your RAM. It also accounts address space — Committed_AS against CommitLimit — not resident memory, so a program that maps generously and touches little is punished for something it never did.
grep -E 'Commit(Limit|ted_AS)' /proc/meminfo
sysctl vm.overcommit_memory vm.overcommit_ratio

# The address space itself
wc -l /proc/<pid>/maps
grep -E '^(Rss|Pss|Private)' /proc/<pid>/smaps_rollupParsing /proc/<pid>/maps as text is no longer the only option: since Linux 6.11 there is a PROCMAP_QUERY ioctl that returns a single VMA in binary form, for tools that would otherwise re-parse a huge text file.
Stage 3 — A page fault makes it real
The first read or write to an address in that range traps into the kernel, which finds a physical page, puts it in the page tables, and returns to the instruction that faulted. Only now does the allocation cost anything.
The distinction that matters operationally is minor versus major. A minor fault is satisfied from memory — a fresh zero page, or a page already in the page cache; a major fault requires disk. A rising major fault rate is one of the cleanest early signals that a machine is short of memory, and it appears long before anything is killed.
ps -o pid,min_flt,maj_flt,rss,comm -p <pid>
grep -E 'pgfault|pgmajfault' /proc/vmstat
vmstat 1 5 # the si/so columns are swap trafficThis is also where the four numbers people confuse each other with come from. VSZ is address space and means little. RSS counts every resident page in full, for every process sharing it, so summing RSS over-counts badly. PSS divides each shared page by its number of sharers, which makes the sum meaningful. USS is not a kernel field at all — private clean plus private dirty, computed by tools — and it is what you would actually get back by killing the process.
smaps_rollup gives you all of it in one cheap read, and is the right first stop. One caveat: PSS is quietly becoming less exact. An experimental option added in Linux 6.15 stops maintaining per-page mapcounts for large folios, which makes Pss approximate for partially mapped folios, and the intention is to make it the default.
Stage 4 — The page has a kind and a size
Two properties now decide everything that happens to this page for the rest of its life.
What backs it. A file-backed page has a copy on disk, so reclaiming it is free if it is clean. An anonymous page has nowhere to go unless there is swap, which is the entire reason a swapless machine under pressure behaves so badly: the kernel can only evict file pages, so it evicts your executables and re-reads them, over and over.
How big it is. Usually 4 KB, but not always — and almost everything written about the exceptions before about 2024 is now out of date in some particular.
cat /sys/kernel/mm/transparent_hugepage/enabled   # always [madvise] never
cat /sys/kernel/mm/transparent_hugepage/defrag    # the latency knob
grep -E 'AnonHugePages|ShmemHugePages' /proc/meminfo
grep AnonHugePages /proc/<pid>/smaps_rollupFour corrections, in order of how often they are got wrong.
defragdefaults tomadvise, notalways. People conflate theenabledanddefragknobs and then blame transparent huge pages for stalls. It isdefrag=alwaysthat makes a process stall in direct reclaim and compaction waiting for a huge page — and that is not the default.- Distributions are split on
enabled. Fedora Workstation and Ubuntu shipmadvise; CachyOS and openSUSE shipalways. “Most distributions default toalways” is a decade-old fact. Check yours rather than assuming either way. neverdoes not mean never. A program callingmadvise(MADV_COLLAPSE)gets huge pages regardless of the global setting.- Large folios in the page cache are not transparent huge pages, have no sysfs control at all, and are on by default — ext4 since Linux 6.16, Btrfs since 7.2. Turning THP off does not turn them off. “I disabled THP, why am I still seeing large allocations” is a real and current confusion, and this is the answer.
There is also multi-size THP, added in Linux 6.8, which allows huge pages between 4 KB and PMD size with per-size controls. It is almost certainly doing nothing on your machine: PMD-sized pages inherit the global setting and every other size defaults to never, and I could not find a distribution that enables any of them.
And the advice that has genuinely cracked: “disable THP, every database says so”. They no longer all say so. MongoDB reversed its position in 8.0 and now recommends enabling transparent huge pages; for 7.0 and earlier it still says disable. PostgreSQL discourages THP but wants explicit huge pages instead — see running PostgreSQL properly. Oracle and SAP HANA still say disable. The blanket rule is dead; the answer is per product and per version. And Linux 6.18 added a better tool than a system-wide switch: a process can call prctl(PR_SET_THP_DISABLE, PR_THP_DISABLE_EXCEPT_ADVISED) to opt itself out of system-wide always while still honouring its own madvise calls, so one badly-behaved application no longer dictates a machine-wide setting.
Stage 5 — It ages on a list
The kernel keeps pages on least-recently-used lists — active and inactive, separately for anonymous and file-backed — and moves them between the two as they are referenced. Reclaim takes from the inactive end. Nothing here costs anything until stage 6; this is bookkeeping that decides who goes first.
Which list gets raided is what vm.swappiness controls, and this is the most confidently repeated wrong tuning advice on the internet.
sysctl vm.swappiness          # default 60, range 0-200
grep -E 'Active|Inactive' /proc/meminfoThe range has been 0 to 200 since Linux 5.8, and the documented meaning is the rough relative I/O cost of swapping versus filesystem paging — not “how eager the kernel is to swap”. At 100 the two are equally expensive; above 100 you are asserting that swap is cheaper than the filesystem, which is exactly true when swap is compressed memory rather than a disk. So the standing advice to “set swappiness to 10” describes a meaning the knob no longer has, and on a machine using zram it is actively harmful: you are telling the kernel to prefer evicting the page cache over compressing anonymous pages into RAM. On a zram system, values well above 100 are the intended usage.
You may also read that the multi-generational LRU replaced all this. It did not. MGLRU was merged in Linux 6.1 and is still not enabled by default in mainline — it needs a kernel built with it and a write to /sys/kernel/mm/lru_gen/enabled — and it is genuinely contested: through 2026 kernel developers have been openly debating whether to improve it, remove it, or unify it with the existing implementation, with real defects on the table. An article calling it “the modern default” is wrong, and one calling it “the future of Linux reclaim” is taking a side in a live argument.
Stage 6 — Pressure builds and reclaim runs
Every memory zone has three watermarks. Above high, nothing happens. Below low, kswapd wakes and reclaims in the background. Below min, an allocating process must reclaim in its own context before it can continue — direct reclaim — and that is the moment your application gets slow for reasons that appear nowhere in its own logs.
Telling those two apart is the most useful measurement in this stage, and the counters are right there:
# Background reclaim is fine. Direct reclaim is your latency.
grep -E 'pgscan_(kswapd|direct)|pgsteal_(kswapd|direct)' /proc/vmstat
grep -E 'allocstall|pgscan_direct_throttle' /proc/vmstat

# Watch the delta rather than the total
watch -n1 "grep pgscan_direct /proc/vmstat"If pgscan_kswapd_* is climbing and pgscan_direct_* is flat, the machine is working and keeping up. If pgscan_direct_* is climbing, processes are stalling to do the kernel’s housekeeping and your latency graph already knows.
Two tunables are worth knowing and mostly not worth changing. vm.min_free_kbytes sets the floor the watermarks are derived from; raising it buys headroom for bursts at the cost of usable memory. vm.watermark_scale_factor defaults to 10, meaning the gaps between watermarks are 0.1% of memory — raising it makes kswapd start earlier and work harder, which is the correct lever when you are seeing direct reclaim on a machine that is not actually out of memory.
One more knob has quietly changed shape. vm.vfs_cache_pressure is no longer a percentage: Linux 6.16 added a companion vfs_cache_pressure_denom, and any writing that calls it “a percentage defaulting to 100” predates the change.
If you want to look at what is actually hot rather than guess, DAMON is now a reasonable answer rather than a research project, built into many distribution kernels. Two things date older instructions instantly: the debugfs interface was removed in Linux 6.14, so anything referencing /sys/kernel/debug/damon/ is broken, and the userspace tool damo now lives under the damonitor organisation.
Stage 7 — Compressed, or written to swap
A clean file page is simply dropped. A dirty one is written back. An anonymous page needs somewhere to go, and that is swap — which on a modern machine is often not a disk at all.
The two compressed options are frequently treated as interchangeable and are not:
| zswap | zram | |
|---|---|---|
| What it is | A compressed cache in front of real swap | A compressed block device used as swap |
| When it fills | Ages cold pages out to the disk behind it | Nothing behind it — it is simply full |
| Needs a swap device | Yes | No |
| Failure mode | Falls back to being slow | LRU inversion: cold pages in fast RAM, hot pages on slow disk |
Fedora has used zram-backed swap by default since Fedora 33, and since Fedora 34 it is sized at 100% of RAM capped at 8 GiB — not the half-of-RAM figure older write-ups quote. For other distributions, check rather than assume.
swapon --show
zramctl                                 # if zram is in use
cat /sys/block/zram0/mm_stat            # orig / compressed / total RAM used
grep -E 'Zswap|SwapCached' /proc/meminfoTwo pieces of swap advice have expired outright. “Swap should be twice RAM” survives only at the very bottom of the range — Red Hat still says 2× below 2 GiB, but above 8 GiB it is “at least 4 GiB”, and the governing sentence is that recommended swap is a function of workload, not of system memory. And “swap costs RAM for its metadata, so skip it on big machines” is obsolete: a rewrite of the kernel’s swap tables across 6.18 to 7.2 has taken that static overhead close to zero. The last technical argument for a swapless server is gone.
Also worth deleting from any config you inherited: zswap.zpool=z3fold no longer works. Both zbud and z3fold were removed in Linux 6.15, leaving zsmalloc as the only allocator, and 6.18 removed the indirection layer they lived behind. This line appears in a great many tuning guides and simply fails now.
This is also the stage where cgroups intervene, and the distinction is the whole thesis of this page in two files. memory.high throttles — going over it never invokes the OOM killer — while memory.max kills. memory.min protects a cgroup unconditionally; memory.low on a best-effort basis. In production you almost always want memory.high with pressure monitoring, and memory.max only as a backstop.
cd /sys/fs/cgroup/system.slice/myservice.service
cat memory.current memory.high memory.max memory.pressure
cat memory.events            # low high max oom oom_kill

# Shrink a workload on purpose, without touching any global sysctl
echo "1G" > memory.reclaim
echo "1G swappiness=max" > memory.reclaim # anonymous pages onlymemory.reclaim is the modern capability most worth knowing about here: proactive, targeted reclaim of one cgroup, on demand, with no global setting involved. Nothing in a 2020-era mental model of Linux memory offers that.
On cgroup v1, the honest answer has two halves. The kernel still compiles it, deprecated and shrinking. But systemd removed cgroup v1 support entirely in version 258, so on a current mainstream distribution v1 is unavailable whatever the kernel supports. Containers, all the way down covers the same split from the container side.
Stage 8 — Something is killed
By the time the kernel OOM killer runs, allocation is already failing and the machine has usually been unusable for a while. Which is why, on most current desktop and server installs, something in userspace kills first.
systemd-oomd watches PSI — the same full figure from the hinge — and acts before the kernel would. Its defaults are a reasonable calibration for “unhealthy”: it acts on memory pressure above 60% sustained for 30 seconds, or swap usage above 90%. Fedora has enabled it by default since Fedora 34, tightening the limit to 50% for user sessions; Ubuntu enabled it in 22.04, to a well-documented wave of complaints about browsers being killed. Check systemctl is-enabled systemd-oomd rather than trusting anyone’s summary, including this one.
The kernel’s own killer scores every candidate from 0 to 1000, essentially in proportion to how much memory it is using — not CPU time, not niceness, not uptime. oom_score_adj, from −1000 to +1000, is added to that score, and −1000 exempts a process entirely.
# Who is the kernel most likely to pick, right now
for p in /proc/[0-9]*; do
  printf '%s %s %s\n' "$(cat $p/oom_score 2>/dev/null)" \
    "${p#/proc/}" "$(cat $p/comm 2>/dev/null)"
done | sort -rn | head

# Who actually did the killing, and how often
systemctl show -p OOMKills,ManagedOOMKills myservice.service
journalctl -k --grep 'oom-kill:'That systemctl show line is new and under-used. systemd 259 added OOMKills and ManagedOOMKills properties on units, counting kernel kills and systemd-oomd kills separately. There is also memory.events per cgroup, whose oom counts OOM conditions and whose oom_kill counts processes killed — they routinely differ.
When you do read the kernel log, grep the structured oom-kill: line rather than the human-readable one, and know which kind of OOM you are looking at:
| Whole machine | One cgroup | |
|---|---|---|
| Kill line | Out of memory: | Memory cgroup out of memory: |
constraint= | CONSTRAINT_NONE | CONSTRAINT_MEMCG |
| Marker | global_oom | the cgroup path |
| Dump | Full zone and node statistics | Cgroup counters only |
One field is misread constantly: task_memcg= names the cgroup of the process being killed, not the cgroup that ran out of memory. It appears in global OOM lines too. If you have been using it to identify which container blew its limit, check constraint= instead.
Two sysctls exist for changing this behaviour and neither is a good idea for a general reader. vm.panic_on_oom reboots instead of killing, defensible only where a fast reboot beats a degraded node. vm.oom_kill_allocating_task kills whoever happened to allocate, which makes the victim effectively random. The modern answers to “it killed the wrong process” are oom_score_adj, memory.oom.group — which kills a whole workload together rather than leaving a broken remainder — and systemd-oomd acting earlier. Signals covers what a SIGKILL does and does not allow a process to do about it.
A worked diagnosis
Back to the application server from the top of the page: two years fine, rebuilt on a newer release, main process lost every few days, service log ending mid-request, free -h showing gigabytes available afterwards.
The hinge settles that in one read, and it has to be taken during the badness rather than after:
$ cat /proc/pressure/memory
some avg10=71.30 avg60=68.44 avg300=52.11 total=9182773451
full avg10=44.02 avg60=41.90 avg300=31.77 total=5510338812full above 40 means that for more than 40% of the time, nothing on the machine was running because everything was waiting on memory. Whatever free said, this machine was in trouble. That eliminates stages 1 to 4 outright and points at reclaim.
$ grep -E 'pgscan_(kswapd|direct)_normal' /proc/vmstat
pgscan_kswapd_normal 88213374
pgscan_direct_normal 41190882      # processes stalling in reclaim themselves

$ swapon --show
NAME       TYPE      SIZE USED PRIO
/dev/zram0 partition 8G   7.9G  100

$ sysctl vm.swappiness
vm.swappiness = 10There it is, and it is a stage 5 problem producing a stage 8 symptom. The rebuilt machine had zram swap — the distribution’s default, which the old machine did not have — and the configuration management had faithfully applied vm.swappiness=10, carried forward from a hardening template written years earlier.
On a zram machine that setting is precisely backwards. Swappiness is the relative cost of swapping versus filesystem paging, and here “swap” is compressed RAM — far cheaper than the filesystem, so the correct value is above 100. At 10 the kernel was told to avoid the cheap option and prefer the expensive one: it left anonymous pages alone, evicted the page cache, and faulted the same executable pages back in from disk over and over. Direct reclaim climbed, PSI climbed, and systemd-oomd — which trips at 60% pressure sustained for 30 seconds — killed the largest thing in the slice.
Which explains the last piece of the confusion. Everyone had been grepping dmesg for the kernel OOM killer and finding nothing, because the kernel never ran it. One command distinguishes them:
$ systemctl show -p OOMKills,ManagedOOMKills myservice.service
OOMKills=0
ManagedOOMKills=6Six kills, none of them from the kernel. The fix was one sysctl — vm.swappiness=150 — plus a memory.high on the service so it would be throttled rather than shot if it genuinely grew. Pressure fell to a normal some with full near zero within minutes.
Three things generalise. Measure delay, not quantity: free answers a question nobody was asking — there was plenty of memory available, and the machine was still dying of memory pressure — and only /proc/pressure/memory is evidence. Stale tuning is worse than no tuning, because a setting someone deliberately applied gets trusted rather than questioned, and swappiness, THP, zswap allocators and swap sizing have all changed meaning in the last few years — if you inherited a sysctl file, find out which lines still mean what they meant when they were written. And a machine’s memory behaviour changes when its distribution changes, not only its workload; zram appeared here without anyone deciding anything. Killing is stage 8 of 8: the question is never “why did the OOM killer choose this process” but “why did reclaim fail”, and where you can, throttle with memory.high rather than kill with memory.max.
Where things go wrong, by stage
| Symptom | Stage | Likely cause | Where to look |
|---|---|---|---|
| Threaded service has a huge RSS for what it does | 1 | glibc arenas — eight per core by default | MALLOC_ARENA_MAX=2 |
| Memory freed but RSS never falls | 1 | Fragmentation below the heap top | malloc_trim() |
| RSS grows in steps and never returns | 1 | The mmap threshold raised itself | strace -e brk,mmap |
| VSZ is enormous and nothing is wrong | 2 | Address space is not memory | smaps_rollup, not ps |
| Allocations fail at half of RAM | 2 | Strict overcommit with the default 50% ratio | CommitLimit in /proc/meminfo |
| A process dies on first write, not on allocation | 3 | Overcommit — the promise could not be kept | The OOM log |
| Application slow with idle CPU and busy disk | 3 | Major faults — re-reading what was evicted | maj_flt; vmstat si/so |
| Summed RSS far exceeds real usage | 3 | Shared pages counted once per process | PSS in smaps_rollup |
| Latency spikes on allocation-heavy work | 4 | defrag=always, not THP itself | transparent_hugepage/defrag |
| Disabled THP, still seeing large allocations | 4 | Page-cache large folios are not THP | Nothing to turn off — by design |
| Database vendor advice contradicts the internet | 4 | The blanket THP rule is dead | That product, that version |
| Page cache evicted while swap sits unused | 5 | swappiness too low for compressed swap | sysctl vm.swappiness |
| Anonymous memory never reclaimed | 5 | No swap at all, or MGLRU generation ageing | swapon --show; lru_gen/enabled |
| Everything intermittently stalls, no process at fault | 6 | Direct reclaim | pgscan_direct_* in /proc/vmstat |
| Bursty allocation fails on a machine with free RAM | 6 | Watermarks too close together | vm.watermark_scale_factor |
| RAM used but no process owns it | 7 | Slab, page tables, Percpu, or compressed pages | slabtop; Zswap in meminfo |
| zram full, machine thrashing anyway | 7 | LRU inversion — no tier behind zram | zramctl; consider zswap |
| Container killed at a limit the host had spare for | 7 | memory.max rather than memory.high | memory.events oom_kill |
| Old tuning file breaks a new kernel | 7 | z3fold removed in 6.15 | Boot parameters and sysctl drop-ins |
Process killed, nothing in dmesg | 8 | systemd-oomd, not the kernel | ManagedOOMKills |
| OOM killer picks the wrong process | 8 | Scoring is proportional to footprint | oom_score_adj; memory.oom.group |
| Half a workload survives the kill and is broken | 8 | One process killed, not the group | memory.oom.group=1 |
| Wrong container blamed for an OOM | 8 | task_memcg= names the victim | constraint= in the same line |
Related reading
- Memory, swap and the OOM killer — the shorter version of this page
- Processes and memory — what a process consists of, and why load average is not CPU
- What happens when you run a program — how the address space is built in the first place
- Containers, all the way down — cgroups from the other side
- Running PostgreSQL properly — huge pages, overcommit and
work_memin a real workload - The life of a write — the page cache from the writing side
- Signals — what
SIGKILLdoes, and why nothing can catch it - systemd beyond services — slices, scopes and where the limits are set
- htop — reading the memory bar without being misled by it