
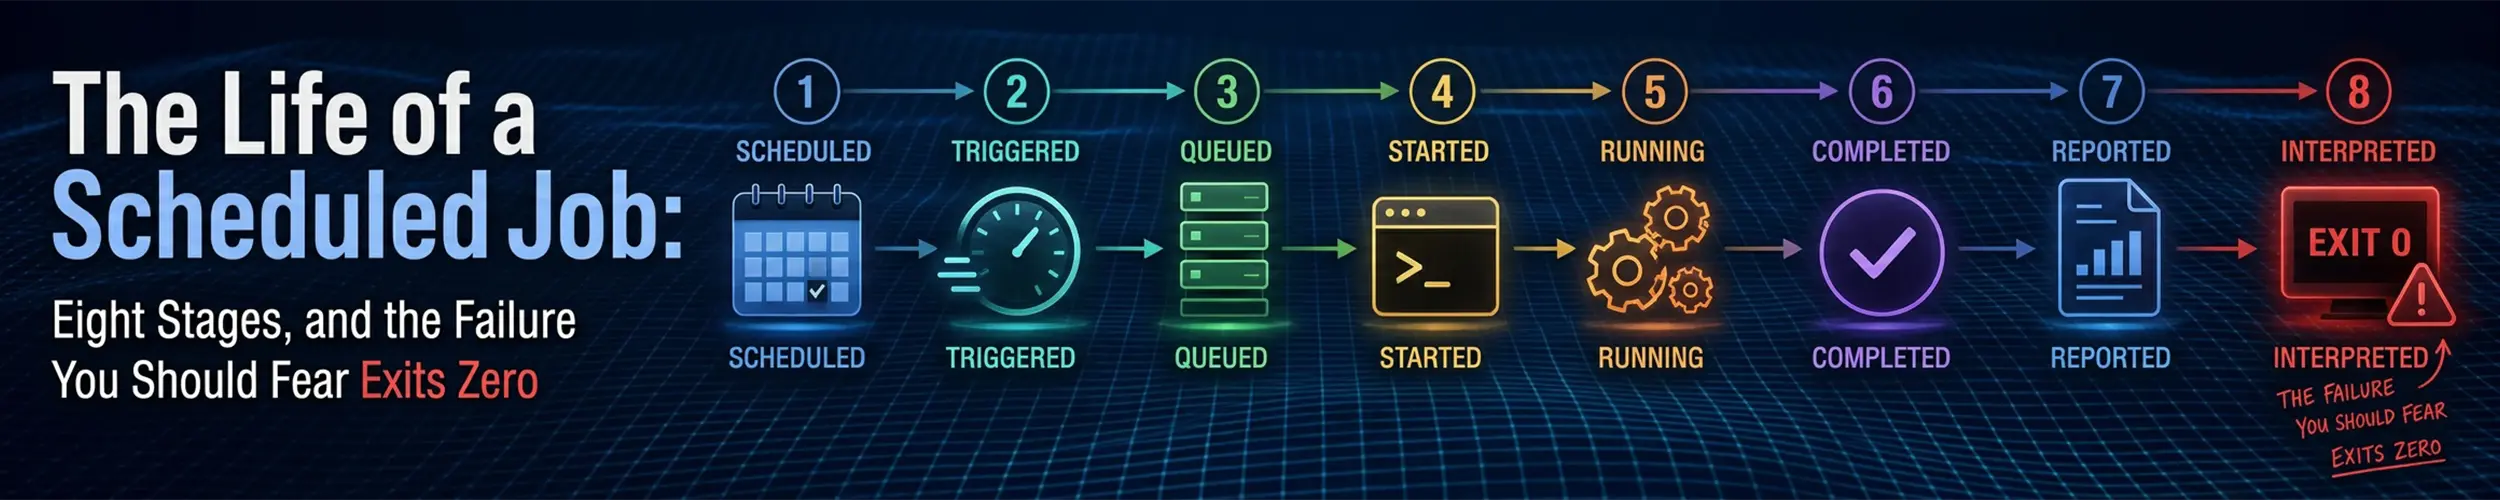
A nightly database backup has run for two years. The storage box has nothing newer than March, nobody was alerted, and the daily report has been clean every morning — because a scheduled job that ran and did nothing looks, on every instrument the machine has, exactly like one that worked. systemctl --failed, OnFailure=, cron’s mail and journalctl -p err are all keyed on a non-zero exit status, and a backup that copies nothing exits zero. This page follows a job through the eight steps between the line you wrote and the person who needed last night’s output, measured on Ubuntu 24.04 with systemd 255 and Vixie cron. It sits below systemd timers and cron, which cover the syntax.
Ten seconds after a successful run, a unit that did its work, a unit that ran and did nothing, and a unit that has never run are identical across ActiveState, SubState, Result, ExecMainCode, ExecMainStatus and InvocationID. systemd returns the unit to inactive (dead) and drops the invocation ID in the same instant. cron writes one line naming the command it launched and nothing else.
The eight steps, and where each one loses you.
- The schedule as written. Accepted is not the same as understood.
- Registration. Enabled, loaded, parsed. Most of the ways a job never runs die here, without becoming a failure.
- The elapse. Accuracy, overrun, catch-up, daylight saving. The schedule that runs is not the one you wrote.
- Exec. An environment owned by PAM or by PID 1, and by neither of you.
- The work. Or, in the case this page exists for, not the work.
- The record. Kept at a priority you did not choose, or discarded because no mail transport exists.
- The reaction.
OnFailure=, a mail, a webhook. All keyed on a non-zero exit. - Off the machine. The only step that asks whether something arrived rather than whether something failed.
If your job is in a crontab, one command tells you where its output has been going:
readlink -e /usr/sbin/sendmail; echo "exit $?"It must be -e; readlink -f prints the path back and exits 0 when nothing is there.
| What comes back | What it means | Go to |
|---|---|---|
A path under /usr/sbin — postfix, exim4, msmtp, nullmailer | Every line your jobs have ever printed went to a local mailbox chosen by whoever installed that package | The record. It exists; read that mailbox, then ask whether anything forwards it off the machine |
Nothing, exit 1 | There is no record of your jobs’ output and there never was one. cron logged No MTA installed, discarding output at info, without naming which job | Off the machine. That record was never kept for you, so nothing on this machine can answer the question. Go to the last section |
If your job is a systemd timer, there is no equivalent reading. Run this against a job that succeeded a minute ago and against one that has never run:
systemctl show backup.service \
  -p ActiveState -p SubState -p Result \
  -p ExecMainCode -p ExecMainStatus -p InvocationID
The two answers are byte-identical: inactive, dead, success, 0, 0, and an empty invocation ID. The sendmail reading is Debian-family packaging, and it tells you where the output went. Nothing on the machine tells you whether the job did its work; that is step eight.
The schedule as written
Both schedulers accept expressions they do not interpret the way the expression reads. OnCalendar=*-*-31 03:00:00 is not a monthly job; it runs on the seven months that have a thirty-first. *-02-29 runs once every four years and is accepted without comment. 0/15 does not parse and *:0/15 is what you meant. Run this before you enable anything:
systemd-analyze calendar --iterations=5 '*-*-31 03:00:00'It prints the normalised form and the next five elapses. One tells you the expression parses; five tell you what it means. Iterations that are not evenly spaced are a different job from the one you thought you were writing.
cron’s surprises are older and documented in crontab(5). Day-of-month and day-of-week combine with or when both are restricted, so 0 3 13 * 5 runs on the thirteenth and on every Friday. A bare % in a command is a newline, so date +%F runs date +; write \%F. And run-parts, which runs /etc/cron.daily, skips any filename containing a dot, so backup.sh is silently ignored where backup runs.
One input to the schedule is not in your file at all. On Debian and Ubuntu, /etc/crontab contains:
25 6 * * * root test -x /usr/sbin/anacron || { cd / && run-parts --report /etc/cron.daily; }Whether every daily job runs at 06:25 by cron or at some other time by anacron depends on whether a package is installed. anacron is absent from a minimal Ubuntu 24.04 image and arrives as a recommendation of several desktop-adjacent packages. Install one of those on a server and the schedule of every daily job changes, with nothing written down to say so.
Registration
Eight timers on one machine: one healthy and seven broken in different ways. A timer written and never enabled; a Unit= naming a service that does not exist; a masked service; a fatal setting in the timer file; a service with a dependency that will fail; a RequiresMountsFor= guard on a path that is not mounted; and a .service enabled instead of its .timer. Then the command everybody recommends for auditing a machine:
$ systemctl list-timers --all
NEXT                         LEFT  LAST PASSED UNIT                 ACTIVATES
Sun 2026-09-06 04:00:00 UTC  9h    -    -      A-control.timer      A-control.service
Sun 2026-09-06 04:00:00 UTC  9h    -    -      D-masked.timer       D-masked.service
Sun 2026-09-06 04:00:00 UTC  9h    -    -      F-depfails.timer     F-depfails.service
Sun 2026-09-06 04:00:00 UTC  9h    -    -      G-mountguard.timer   G-mountguard.service
-                            -     -    -      C-noservice.timer    C-noservice.service
-                            -     -    -      E-badunit.timer      E-badunit.service
- - - - fstrim.timer fstrim.serviceTwo of the eight are missing. The timer that was never enabled is absent, and so is the one whose .service was enabled instead. --all means every timer that is loaded, and a unit that was never started is not loaded. The single most common scheduling mistake is invisible in the command recommended for finding it.
NEXT = - covers four unrelated conditions: the service does not exist, the timer file has a fatal setting, the service is masked, and a healthy timer whose condition is not currently met. fstrim.timer above is the fourth case and is fine. systemctl --failed shows none of the eight, because none has run. systemctl status on the four that look healthy prints a green dot and active (waiting) for each, the masked one included.
systemd-analyze verify is a syntax check, not a reference check. A timer whose Unit= names a service that does not exist verifies silently and exits 0. A misspelt directive is reported on stderr and exits 0. Read its output; do not test its exit status.
cron’s version of this step has one trap. A malformed file in /etc/cron.d never runs and produces nothing under the identifier its jobs use. It is logged, under a different one:
cron[1879]: Error: bad username; while reading /etc/cron.d/nouser
cron[1879]: (*system*nouser) ERROR (Syntax error, this crontab file will be ignored)Per-job lines are tagged CRON; the daemon’s own complaints are tagged cron. journalctl -t CRON misses this, and grep CRON is case-sensitive and misses it too. journalctl -u cron catches both.
The elapse
OnCalendar=*-*-* 02:30:00 does not run at 02:30:00. The default AccuracySec= is one minute, so systemd may fire anywhere in the following sixty seconds to coalesce your wakeup with somebody else’s. Two isolated timers, default accuracy against AccuracySec=1us:
default (nominal :17)        tight (nominal :43)
  18:27:24.492   +7.5s         18:26:43.012   +12ms
  18:28:39.904  +22.9s         18:27:43.016   +16ms
18:29:31.209 +14.2s 18:28:43.012 +12msSeven to twenty-three seconds late, different every time. list-timers prints the nominal time, the journal records the actual one, and nothing prints the difference. RandomizedDelaySec= stacks on top and re-randomises on every elapse.
OnUnitActiveSec= measures from the last activation, not the last completion. A thirty-second timer on a ninety-second job:
18:20:22.084  start pid=2818
18:21:52.089  end   pid=2818
18:21:52.104  Starting slow90.service ...     <- immediately
18:21:52.107  start pid=2877
18:23:22.111  end   pid=2877
18:23:22.132 start pid=2936Back to back with no gap, three elapses dropped, and no line in the journal saying any elapse was missed. This is what “timers prevent overlapping runs” costs: your interval is replaced by the job’s duration. Use OnCalendar= for anything whose period matters.
Persistent=true is a zero-byte file at /var/lib/systemd/timers/stamp-NAME.timer whose mtime is the whole record, so touch on it changes catch-up behaviour. A three-day gap on a daily schedule produces one catch-up run, not three. For a nightly backup that is fine; for a daily report or a rotation named by date, six missed days produce one run and five absent outputs, and nothing counts them.
Daylight saving, which How Time Works owns: at a spring-forward, a job in the missing hour loses that day on both schedulers. At a fall-back a systemd timer fires once; “your job runs twice” is a cron result. The timer hazard is that consecutive daily runs are twenty-five hours apart in autumn and twenty-three in spring. The advice for this is usually:
[Timer]
OnCalendar=*-*-* 02:30:00
Timezone=UTCThere is no Timezone= directive in [Timer]. systemd 255 logs Unknown key name 'Timezone' in section 'Timer', ignoring, starts the timer, and computes the elapse in local time. The working form is a suffix inside the expression:
OnCalendar=*-*-* 02:30:00 UTCExec, and whose environment it is
The received wisdom is that a cron job has a stripped-down environment and a systemd timer is the predictable one. On Ubuntu 24.04 that is backwards. One script reading its own /proc/$$/environ, run both ways on the same machine at the same time:
--- a systemd service, root, no User=, no Environment=  (six variables)
INVOCATION_ID=80ba0e7981df47b98637b00e0843d67b
JOURNAL_STREAM=9:24300
LANG=C.UTF-8
PATH=/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin
SYSTEMD_EXEC_PID=813
USER=root

--- a cron job, root  (five variables)
HOME=/root
LOGNAME=root
PATH=/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin:/sbin:/bin:/usr/games:/usr/local/games:/snap/bin
PWD=/root
SHELL=/bin/shThe cron job’s PATH is the full login PATH, /snap/bin included. The service’s is shorter, with no /sbin, no /bin and no HOME at all. A script that calls a snap, or something in /sbin by bare name, or ends with cd "$HOME", works under cron and fails under a timer.
The mechanism: Ubuntu runs cron -f -P, and /etc/pam.d/cron includes pam_env.so. cron is a PAM application. pam_env reads /etc/environment, and -P tells cron not to overwrite the result with its compiled-in /usr/bin:/bin. The same is true of /etc/default/locale, which gives the cron job a real LANG, and of /etc/security/limits.conf, which moves the cron job’s ulimit -n and does nothing for a service. Remove -P and the old folklore comes back exactly. Check your own machine:
systemctl cat cron.service | grep ExecStart
printf '* * * * * /usr/bin/env > /tmp/cronenv\n' | crontab -Two consequences. Every cron job on the machine shares one cgroup, /system.slice/cron.service, so MemoryMax=, CPUQuota= and per-job attribution are unavailable for cron as a class; each timer’s service gets its own. And systemctl --user fails from both with Failed to connect to bus: No medium found. loginctl enable-linger starts the user manager but a process with no XDG_RUNTIME_DIR still cannot reach it:
XDG_RUNTIME_DIR=/run/user/$(id -u) systemctl --user list-timersThe work, or not the work
Seven scripts under identical timers. One copies a file. Six run, exit zero and copy nothing: a wrong working directory; an empty glob with nullglob unset, so the copy of a nonexistent file sits inside an if that swallows it; a for over nothing with nullglob set; a lock it could not take and treated as “nothing to do”; a set -e exit masked by a trailing true; and a pipeline failure swallowed because pipefail was unset.
UNIT            RESULT    EXIT  ACTIVE    JOURNAL LINES
s0-control      success   0     inactive  4
s1-wrongcwd     success   0     inactive  3
s2-emptyglob    success   0     inactive  3
s3-nullglob     success   0     inactive  3
s4-lock         success   0     inactive  3
s5-seteearly    success   0     inactive  3
s6-pipe success 0 inactive 4The three journal lines are the same for all seven: Starting, Deactivated successfully, Finished. systemctl --failed lists none. OnFailure= was configured on all seven and fired for none. Under cron the same seven produce seven identical (root) CMD (...) lines. The control is distinguishable by one thing: it prints the word copied, because its author made it.
A scheduled job has three outcomes, not two. It can fail, which every instrument on the machine catches. It can work. And it can complete: run to the end, exit zero, produce nothing. No instrument the operating system offers distinguishes completing from working, and completing is the common case, because almost every way a script can quietly do nothing ends in a successful exit.
The pipeline job did leave evidence:
18:26:54.793  s6-pipe.sh[3533]: cat: /lab/src/DOES-NOT-EXIST.txt: No such file or directory
18:26:54.794 systemd[1]: s6-pipe.service: Deactivated successfully.An error and a success verdict, 1.3 milliseconds apart, in the same unit’s journal, both at priority 6. journalctl -u s6-pipe.service -p err returns nothing.
The record
Five jobs, identical except for what they printed and what they exited with, under both schedulers on a machine with no mail transport, which is the default state of every minimal cloud image. Everything cron recorded about that minute:
CRON[2506]: (root) CMD (/lab/j/silent3.sh)
CRON[2509]: (root) CMD (/lab/j/out0.sh)
CRON[2508]: (root) CMD (/lab/j/silent0.sh)
CRON[2511]: (root) CMD (/lab/j/fail3.sh)
CRON[2512]: (root) CMD (/lab/j/err0.sh)
CRON[2505]: (CRON) info (No MTA installed, discarding output)cron never records an exit status. The job that exited 3 having written to both streams and the job that exited 0 having written nothing produced one identical line each. Every marker the jobs printed appears zero times in the journal, and /var/mail is empty. The discard is logged once, at priority 6, without naming the job, and the PID on it is the PAM session parent rather than the job’s.
systemd keeps everything cron loses, and the priorities are the point:
p6 info     fail3.sh   STDOUT-from-fail3 marker-C
p6 info     fail3.sh   STDERR-from-fail3 marker-D
p5 notice   systemd    j-fail3.service: Main process exited, code=exited, status=3/NOTIMPLEMENTED
p4 warning  systemd    j-fail3.service: Failed with result 'exit-code'.
p3 err systemd Failed to start j-fail3.service - job fail3.stderr is not promoted; both streams arrive at priority 6. The identifier is the executable’s basename, so journalctl -t backup finds nothing where backup.service runs backup.sh. And therefore:
$ journalctl -u j-fail3.service -p err
Failed to start j-fail3.service - job fail3.
Failed to start j-fail3.service - job fail3.-p err shows systemd’s verdict and hides your script’s explanation of it. Drop the flag. The Life of a Log Line has the general form: priority is a fact about who wrote the line, not about how bad the news is.
The reaction
Everything the operating system offers to react on your behalf is keyed on a non-zero exit. OnFailure= activates on a failed state, systemctl --failed lists units that exited non-zero, cron’s mail is triggered by output, and -p err filters on a priority only systemd’s verdict reaches. The seven scripts above exited zero and all four were quiet. The most-recommended guard fails in the case it exists for:
[Unit]
RequiresMountsFor=/backupThis creates a dependency on whichever mount unit currently covers the path. If /backup is an ordinary directory on the root filesystem, because the fstab line was never added or the disk went away and the directory remained, it resolves to After=-.mount, which is always active:
$ mountpoint /backup
/backup is not a mountpoint
$ systemctl show G-mountguard.service -p After | tr ' ' '\n' | grep mount
After=-.mount
$ journalctl -u G-mountguard.service | tail -3
Starting G-mountguard.service ...
echo[3270]: ran-G-EVEN-THOUGH-BACKUP-IS-NOT-MOUNTED
Finished G-mountguard.service.A mountpoint -q /backup || exit 1 at the top of the script is not belt and braces alongside RequiresMountsFor=; it is the only one of the two that does the job. One more, from more daily-report scripts than anything else:
systemctl --failed --no-legend || echo "  none"        # never prints none
systemctl --failed --no-legend | grep -q . || echo "  none"   # does
systemctl --failed exits 0 when nothing has failed, so the first line prints an empty section every morning. OnFailure=alert@%n.service, where most writing on this subject stops, closes the case where a job runs and fails. It cannot close the case where a job completes, and it cannot close the case where a timer never fired, because a service that never activated has nothing to fail.
Off the machine
Steps 1 to 7 all ask did something go wrong? and all answer no for a job that ran and did nothing. The last step asks did something arrive?, and a watcher keyed on absence has to live somewhere the job is not, because one that shares the scheduler shares its failure modes. Two shapes, both older than systemd:
- A dead-man’s switch. The job checks in when it has done its work; something off the machine alerts when the check-in does not arrive. This catches the job that completed, the job that never fired, and the machine that was off.
- A freshness check on the output. The job writes a timestamp file, or you check the age of the newest artefact against the schedule, from where the output lands.
Monitoring Without a Full Observability Stack builds both. systemd 249 added the hook a dead-man’s switch needs:
[Unit]
OnSuccess=backup-checkin.serviceA unit activated when this one succeeds, the only hook in the sequence keyed on something happening rather than something going wrong. It is half a fix: it fires on exit zero, so a job that completed and did nothing checks in as cheerfully as one that worked. The honesty has to live in the script, as a mountpoint -q or a “did I copy anything” check.
A worked diagnosis
Back to the backup from the top of the page: two years of nightly runs, nothing on the storage box newer than March, no alert, and a clean daily report every morning.
$ systemctl status backup.timer
● backup.timer - nightly database backup
     Active: active (waiting) since Mon 2026-01-06 09:12:41 UTC
    Trigger: Sun 2026-09-06 02:30:00 UTC; 8h left
$ systemctl --failed
0 loaded units listed.Green, waiting, nothing failed. The Trigger line is the one real fact: the timer is loaded and has a next elapse, which rules out the two registration faults that keep a timer out of list-timers.
$ journalctl -u backup.service --since "3 days ago" | grep -c Finished
3
$ journalctl -u backup.service -n 3 --no-pager
Starting backup.service - nightly database backup...
backup.service: Deactivated successfully.
Finished backup.service - nightly database backup.It ran, three nights out of three. Three lines and no fourth, which is what a well-behaved script produces when it thinks everything is fine.
$ systemctl show backup.service -p InvocationID -p Result -p ExecMainStatus
InvocationID=
Result=success
ExecMainStatus=0Identical to a unit that has never run. The evidence is not on the unit; it is in the filesystem the job wrote to.
$ ls -t /backup | head -2
db-2026-09-05.sql.gz
db-2026-09-04.sql.gz
$ mountpoint /backup
/backup is not a mountpoint
$ df -h /backup /
Filesystem      Size  Used Avail Use% Mounted on
/dev/vda1       900G  611G  243G  72% /
/dev/vda1 900G 611G 243G 72% /The backups exist and are current, on the root disk. /backup stopped being a mount point in March, when the volume was detached during a reboot and the fstab entry did not survive. The empty directory was still there, so every night since, the job has written a good backup to the system disk of the machine it is backing up. RequiresMountsFor=/backup resolved to -.mount and let it through, and six months of nightly dumps are now on the system disk.
The fix is three lines and only one is the mount: mountpoint -q /backup || exit 1 at the top of the script, the fstab entry restored, and a check on the age of the newest file on the storage box, run from the storage box. Only the third would have caught this in March, and it also catches the empty-glob version, the wrong-directory version, and the night the machine was off.
Before you call it done
systemd-analyze calendar --iterations=5on the expression, and the five elapses evenly spaced unless you meant otherwise- The
.timerenabled, not the.service, and the name present insystemctl list-timers - The script’s own guard on the thing it cannot do without:
mountpoint -q, a non-empty source, a lock it takes or fails on. NotRequiresMountsFor=alone set -euo pipefail, and no trailingtruethat undoes it- The job printing one line saying what it did: a count, a size, a filename
- The environment checked the way it will run:
systemd-run --unit=t1 /path/to/script, or one crontab line writingenvto a file - Something off the machine that alerts on absence: a check-in that stops arriving, or the age of the newest output checked from where it lands
Related reading
- systemd Timers — the unit files, the directives and the syntax
- cron — crontab syntax, the directory drops and the escaping rules
- Monitoring Without a Full Observability Stack — the dead-man’s switch and the freshness check, built
- Automated Backups — the job most exposed to everything on this page
- How Time Works on a Linux Machine — the clock underneath the elapse
- The Life of a Log Line — who wrote each field, and why priority is a fact about the author
- The Life of a Login — where
PATHreally comes from - The Life of a Network Interface — why a boot-time job can find no network while
network-online.targetis active, and what the three wait-online programs actually wait for - The Life of a Reload — the same shape for a reload: exit 0 is a statement about a command, not about the outcome